
外观
Gemini 1.5 Pro 使用指南
Google 推出的 Gemini 1.5 Pro 是计算效率较高的多模态混合专家模型,重点增强对长篇内容的检索与推理。它可以处理包含数百万词元的文档,以及数小时的视频和音频。
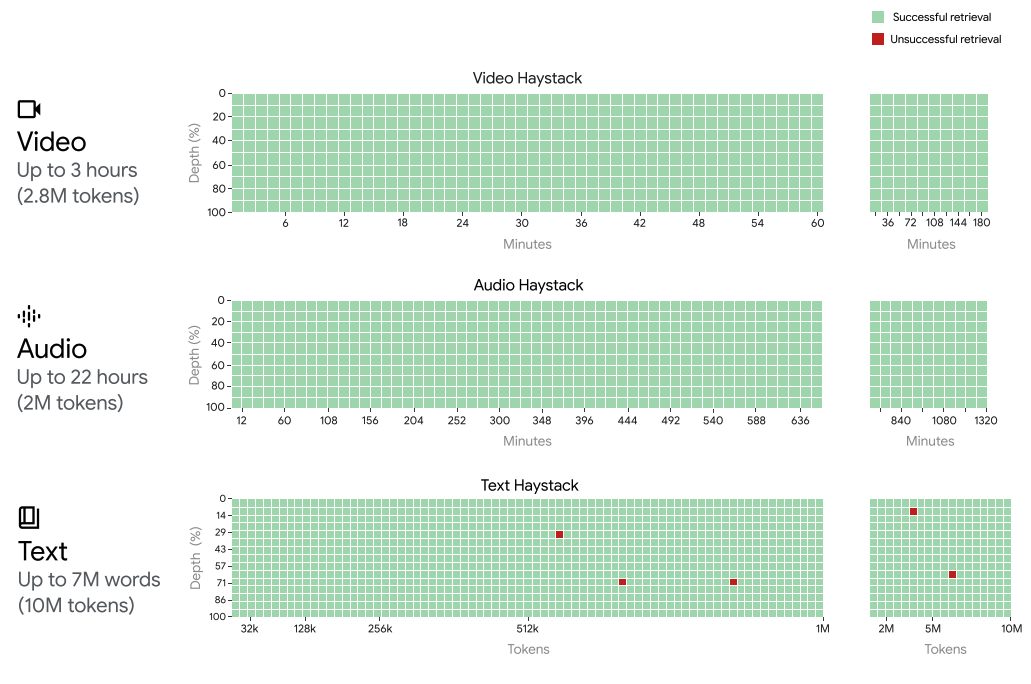
原文报告称,模型改善了长文档问答、长视频问答和长上下文自动语音识别的表现,在标准基准中达到或超过 Gemini 1.0 Ultra,并在至少 1,000 万词元范围的检索实验中实现超过 99% 的召回率。
发布时,Google 还在 AI Studio 中提供实验性的 100 万词元上下文版本。原文以此前公开模型约 20 万词元的窗口作为对照,说明其可用于大型 PDF、完整代码仓库和长视频问答,并支持在同一输入序列中混合音频、图像、文本与代码。
架构
Gemini 1.5 Pro 是基于 Transformer 的稀疏混合专家(MoE)模型,继承 Gemini 1.0 的多模态能力。MoE 可以增加总参数量,同时保持每次激活参数数量相对稳定。
技术报告没有披露很多细节,但指出该模型训练计算量显著减少、部署效率更高,并通过架构变化支持最长 1,000 万词元的理解实验。模型使用多模态数据预训练与指令微调,再根据人类偏好进一步调整。
结果
Gemini 1.5 Pro 在文本、视频和音频中,均展示了最长 100 万词元范围内接近完美的“大海捞针”召回表现。原文用以下规模说明其能力:
- 约 22 小时录音。
- 十本各 1,440 页的书。
- 完整代码库。
- 按每秒一帧处理的三小时视频。
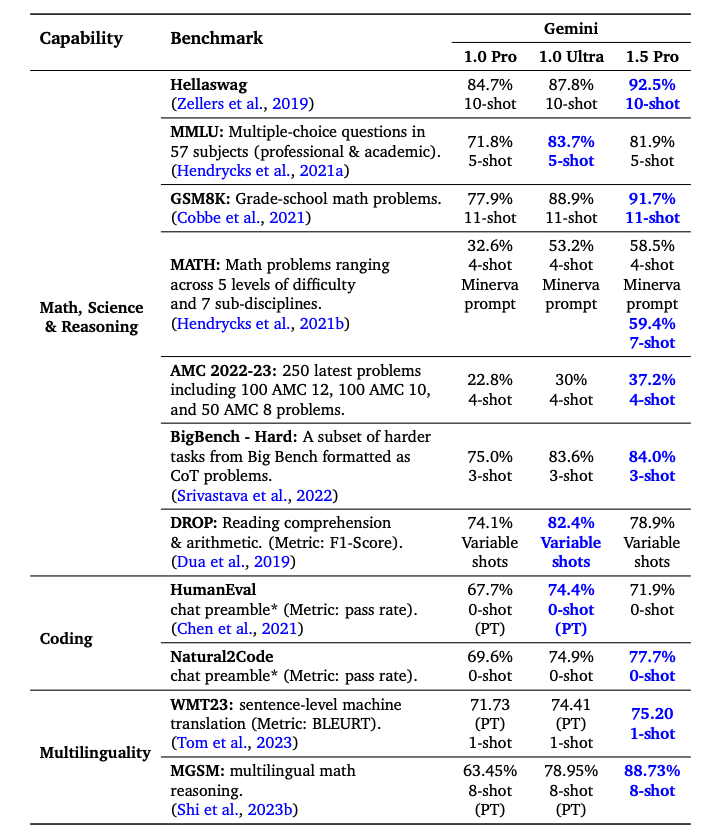
模型在多数基准上超过 Gemini 1.0 Pro,尤其是数学、科学、推理、多语言、视频理解和代码任务。虽然训练计算量少得多,它仍在约一半测试中超过 Gemini 1.0 Ultra。
能力与示例
下面介绍大规模数据分析和长上下文多模态推理等能力,信息来自论文、社区和原作者实验。
长文档分析
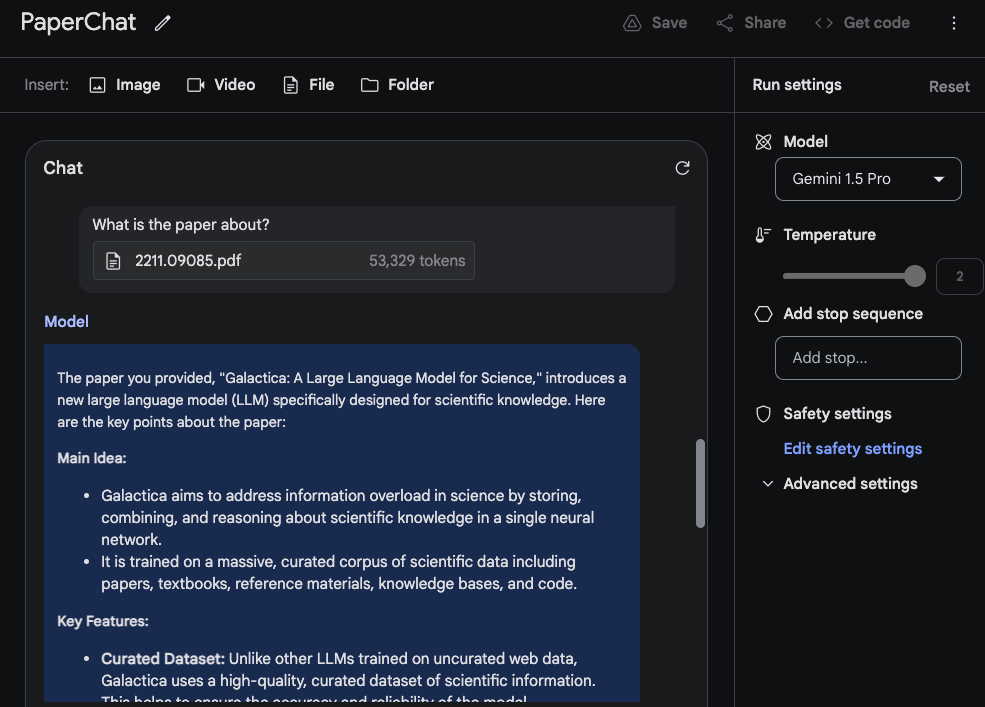
在 Google AI Studio 的 100 万词元版本中,可以上传完整 PDF。下面上传一篇论文,并询问“这篇论文讲什么?”:
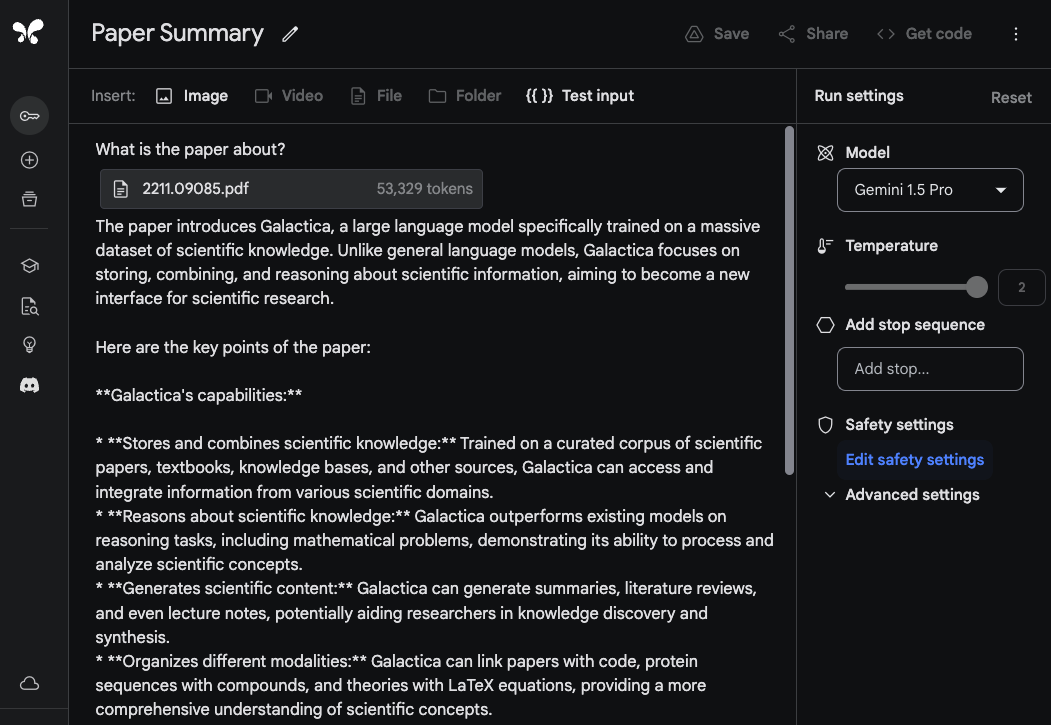
模型给出了准确、简洁的 Galactica 论文摘要。除了自由格式提示,也可以通过聊天形式针对上传文档连续提问。
接下来上传两篇 PDF,提出需要同时参考两篇文档的问题:
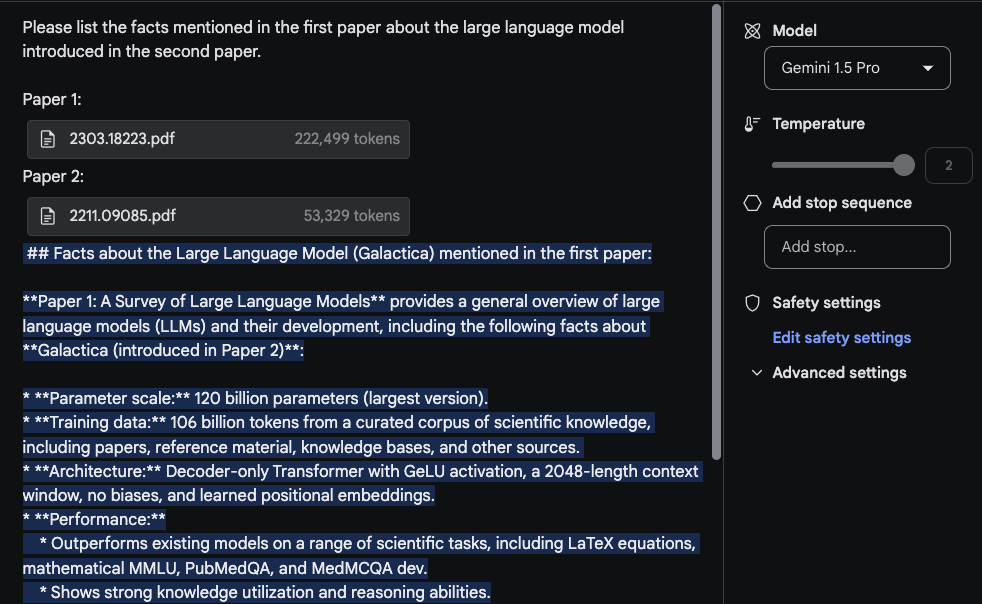
回答总体合理。第一篇是大语言模型综述,模型从其中的表格提取了信息,“架构”部分看起来也正确。但“性能”部分不应出现,因为第一篇论文没有这段内容。
这个任务中,原作者将“请列出第一篇论文中关于第二篇论文所介绍模型的事实”放在最前面,并用 Paper 1、Paper 2 标记论文。后续还可以尝试上传多篇论文撰写相关工作章节,或把较新的模型研究加入既有综述。
视频理解
Gemini 1.5 Pro 从训练开始就具备多模态设计。原作者用 Andrej Karpathy 的大语言模型讲座测试视频理解。
在聊天提示中上传 YouTube 讲座视频,先问“这节课讲什么?”,模型能够较准确地总结。
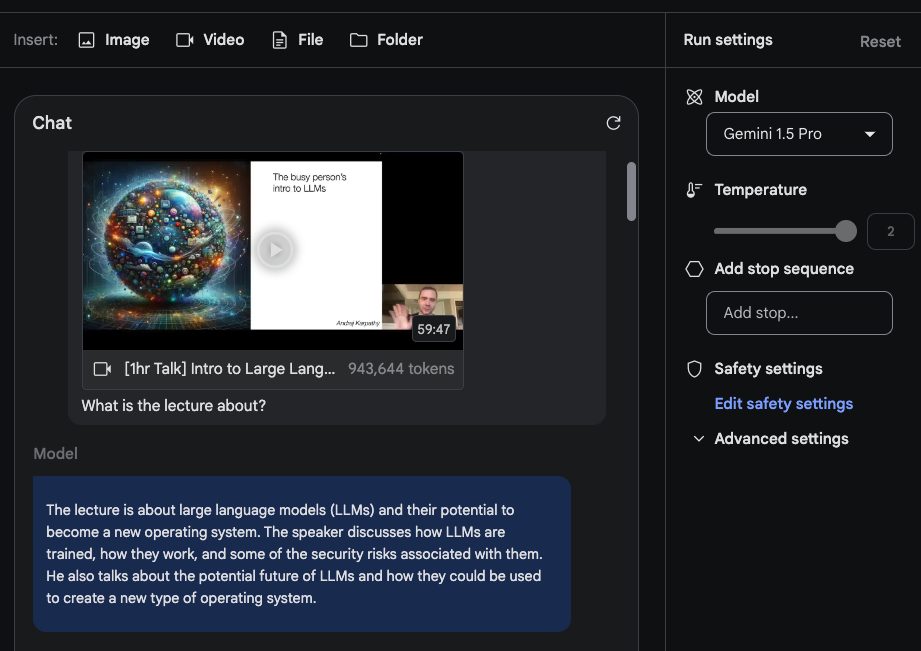
随后要求生成一页长度的简明提纲,下面保留经过删节的原始输出:
markdown
## Large Language Models: A New Operating System?
Introduction:

- LLMs are trained on massive amounts of text data and can generate human-quality text.
- They are becoming increasingly powerful and are being used for a wide range of tasks, such as writing, translation, and coding.

How LLMs Work:

- LLMs are neural networks that predict the next word in a sequence.
- They learn by iteratively adjusting their parameters to make better predictions.
- While we can measure their performance, we don't fully understand how the billions of parameters collaborate to achieve it.

Training LLMs:

- Requires massive amounts of data and computing power.
- Can be thought of as "compressing the internet" into a single file.
- For example, training LLaMA 2 70B required 6,000 GPUs for 12 days and cost ~$2 million.

LLM Security:

- LLM security is a new and rapidly evolving field.
- Some key security risks include:
    - Jailbreaking: bypassing safety mechanisms to generate harmful content.
    - Prompt injection: injecting malicious code into prompts to control the LLM's output.
    - Data poisoning / Backdoor attacks: inserting crafted text into the training data to influence the LLM's behavior.
...
摘要较简洁,包含讲座的主要结构与要点。原作者没有核实全部内容,但注意到模型提取了“训练 LLaMA 2 70B 使用 6,000 张 GPU、持续 12 天、成本约 200 万美元”等具体信息。
如果细节很重要,仍需警惕幻觉或错误检索。例如,询问讲座中 Llama 2 的 FLOPs 时,模型回答约一万亿次,而正确值应是约 1e24 FLOPs。技术报告也记录了长上下文模型回答视频细节时的失败案例。
另一项任务是提取视频中的表格。模型生成了表格,列标题正确,但把 Coref Resolution 误写为 Concept Resolution。原作者在其他表格及文本框提取任务中也观察到类似不一致。
技术报告还展示了根据场景或时间戳检索视频内容的能力。下面询问某个章节从何时开始。
提示词:
At what timestamp does the LLM OS section start?输出:
The LLM OS section starts at 42:17.这一回答正确。
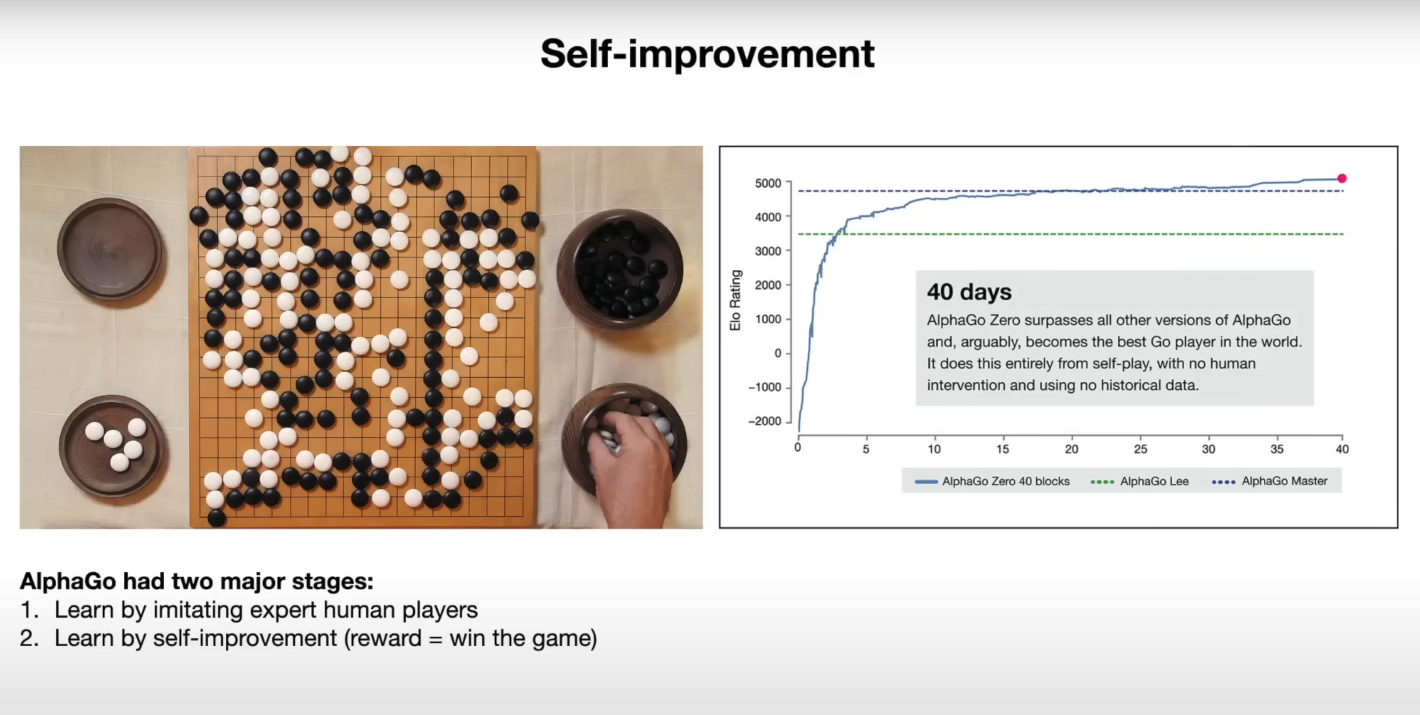
下一个示例要求解释幻灯片中的图表。
提示词:
Can you explain the chart (on the right-hand side) on the self-improvement slide?输出:
The chart shows the performance of AlphaGo Zero over time, as measured by its Elo rating. The Elo rating is a measure of a player's skill in a game, with higher ratings indicating stronger players. The chart shows that AlphaGo Zero's performance improved rapidly over the course of 40 days, eventually surpassing the performance of all other versions of AlphaGo, including the version that defeated the world champion Go player Lee Sedol. This improvement was achieved entirely through self-play, with no human intervention or historical data.模型较好地利用了视频信息解释图表。对应幻灯片如下:
代码推理
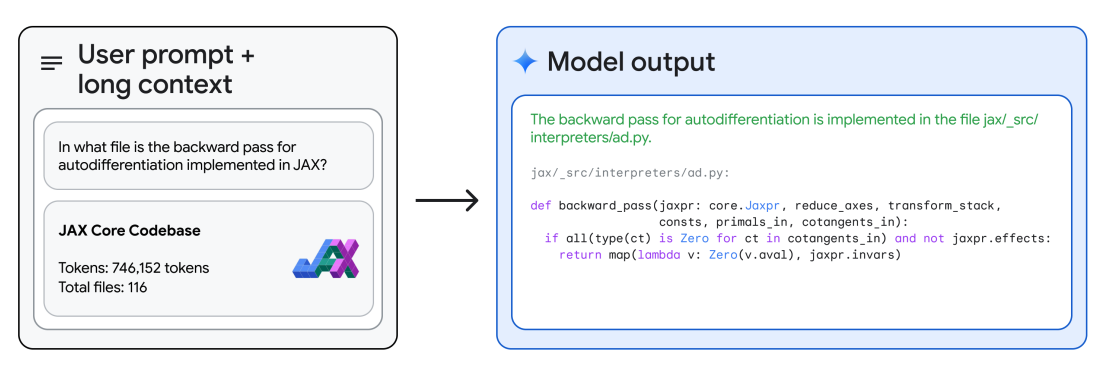
长上下文让模型能够回答整个代码库的问题。Google AI Studio 支持上传多达 100 万词元的代码,再提出各种编程任务。
技术报告中的例子将完整 JAX 代码库(约 74.6 万词元)放入上下文,要求定位核心自动微分方法。
英语到 Kalamang 语翻译
Kalamang 是全球使用者少于 200 人的语言。研究向模型提供约 500 页语法资料、词典及约 400 个平行句子,模型从英语翻译到 Kalamang 的水平,接近依据同样材料学习的人类。
这展示了长上下文支持的上下文学习能力。
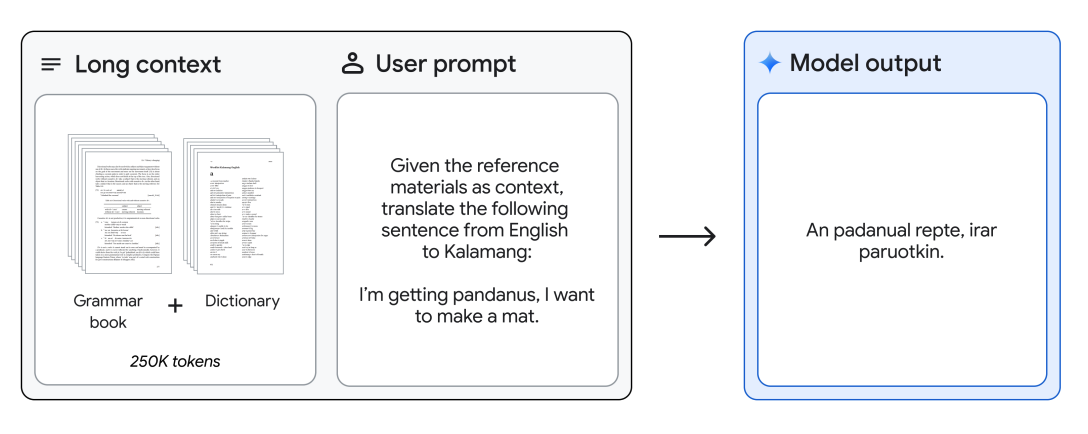
图片来源:Gemini 1.5 技术报告。